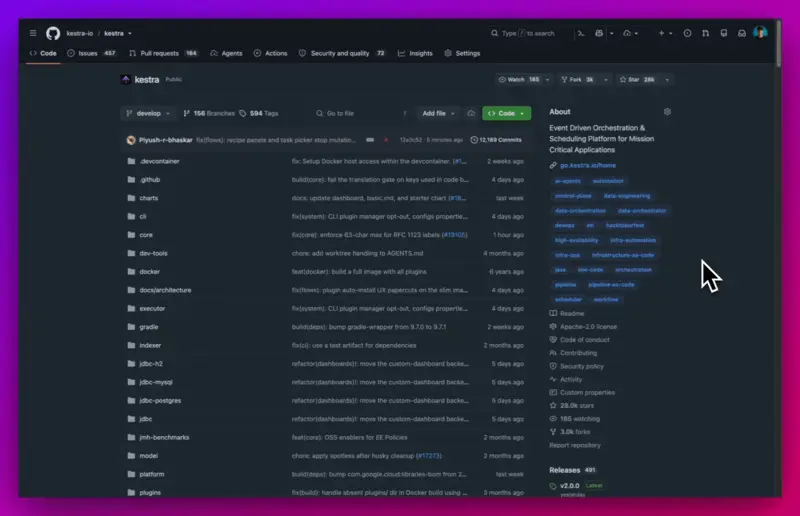
Kestra is an open-source platform for scheduling and chaining data, AI and infrastructure workflows, built around YAML definitions and a web UI. It is aimed at data and engineering teams who need to automate multi-step jobs.
Jitsu collects event data from websites, apps and servers and sends it to data warehouses and other tools. It is aimed at data teams who want to run that pipeline themselves or use a hosted version.
1.8kActiveWindows · Mac · Linux · AndroidApache-2.0Replaces partlyFor developers
Bruin is a command-line tool that moves data from other sources into a database, transforms it with SQL, Python or R, and checks its quality. It is for data engineers and analysts who want these steps in one framework.
1.7kActiveMITReplaces partlyRuns on your own server
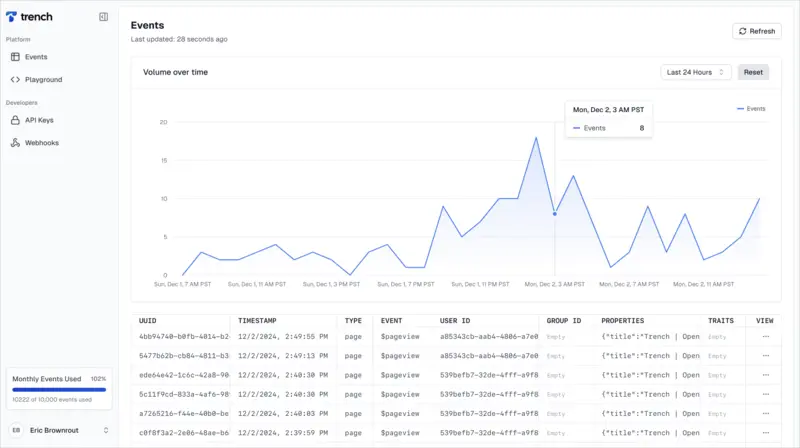
Trench is a system for recording and querying events that happen in apps and websites, such as button clicks or sign-ups. It is aimed at teams that want to run their own analytics pipeline and keep their data.
Runs on your own server · GitHub
None of these match. Try another device.
Before you build
Planning something for an alternative to Hightouch? See what exists first, so you can reuse parts or explain what's different. Paste this into any AI assistant:
Read the list of open-source alternatives at https://opensourceeverything.org/data/groups/data-pipelines.json. Compare it with my project or idea below. Tell me which projects overlap, what I could reuse instead of rewriting, and what mine does that none of them do.
My project or idea:
Here is a list of open-source alternatives to Hightouch, from Open Source Everything (CC BY-SA 4.0):
- Kestra (Apache-2.0, https://github.com/kestra-io/kestra; replaces fully): Kestra is an open-source platform for scheduling and chaining data, AI and infrastructure workflows, built around YAML definitions and a web UI. It is aimed at data and engineering teams who need to automate multi-step jobs.
- Jitsu (MIT, https://github.com/jitsucom/jitsu; replaces fully): Jitsu collects event data from websites, apps and servers and sends it to data warehouses and other tools. It is aimed at data teams who want to run that pipeline themselves or use a hosted version.
- Bruin (Apache-2.0, https://github.com/bruin-data/bruin; replaces partly): Bruin is a command-line tool that moves data from other sources into a database, transforms it with SQL, Python or R, and checks its quality. It is for data engineers and analysts who want these steps in one framework.
- Trench (MIT, https://github.com/FrigadeHQ/trench; replaces partly): Trench is a system for recording and querying events that happen in apps and websites, such as button clicks or sign-ups. It is aimed at teams that want to run their own analytics pipeline and keep their data.
Compare it with my project or idea below. Tell me which projects overlap, what I could reuse instead of rewriting, and what mine does that none of them do.
My project or idea: